About Me
A little about me and my background, and my journey in software development.
Who I Am
I'm Ahmed Ikram, a final-year Computer Science student at the University of Dundee specialising in Data Science and AI, on track for a First-Class degree and graduating in June 2027. I build across the stack, LLM systems in Python, full-stack platforms in TypeScript and React, and data pipelines on AWS, Azure and GCP.
I hold AWS Academy certifications in Cloud Foundations and Machine Learning, plus a Foundations of Azure AI certification, all completed independently alongside full-time study.
What I've Built
My strongest work ships end-to-end with real guardrails. LAAD began as a 7-person university team project - after the module I rebuilt it solo: LangGraph hybrid RAG (0.708 vs 0.350 recall), 3-layer anomaly detector (0.70 F1) on a live Kafka stream, plus a full Kafka pipeline and AWS/Terraform deploy, with OpenTelemetry/Jaeger distributed tracing across services.
Solo: SWE-Qwen (model-agnostic LLMOps, fine-tuned Qwen3-14B, 7× fix rate), StockLens (Rust + LSTM with automated weekly retraining, self-built MCP), DevSync (1,520 tests, k6 gate, live on GKE), WikiStream (58.9M+ events, zero loss) and an Azure ETL → Power BI platform. All gated for real users - CI blocks RAGAS regress >0.05, promos need sig tests, streams hold at-least-once under chaos, zero long-lived creds. Six projects hold 8,378 automated tests in total.
What I'm Looking For
I'm looking for a graduate role in AI engineering, data engineering, or software engineering, starting July 2027 after I graduate in June. I want to contribute to production systems alongside experienced engineers, and I'm open to any sector. I'm based in Dundee but open to relocation across the UK.
My Projects
My strongest work, shipped end-to-end - AI systems, streaming pipelines, and full-stack platforms. Featured projects lead; earlier coursework follow
Featured Work
StockLens
Scan a receipt, then buy or sell real stocks at live market prices with the extracted cash; track portfolios with Global LSTM 5-day forecasts and an AI agent - all 16 tools behind a self-built MCP server (OAuth 2.1 PKCE). A weekly Airflow pipeline retrains the Global LSTM (5-seed probability ensemble) with McNemar-gated champion/challenger promotion and Evidently drift detection. FastAPI + PyTorch + LangGraph + Rust backend, with 2,417 automated tests.
W3C Web Logs ETL Pipeline
Serverless Databricks DLT pipeline ingesting 93 W3C IIS log files through a Bronze→Silver medallion architecture into Azure SQL via pymssql export, transformed via dbt into a star schema with Power BI-ready exports, orchestrated by Airflow, provisioned with Terraform, with 750 automated tests.
DevSync
Real-time project tracker where performance regressions can't ship - project-scoped Socket.IO rooms fanned out cluster-wide via Redis, GitHub OAuth 2.0 with bidirectional Issue/PR sync, and a k6 load gate measuring P95 against a committed baseline (P95 ≤500ms, P99 ≤1s, <1% errors at 10 VUs). Flask + PostgreSQL + React live on GKE at gcp.devsyncapp.me - per-PR preview environments, External Secrets over GCP Secret Manager, Cloud SQL, a Trivy/cosign/SBOM supply chain, and Terraform-owned infra with OIDC-only CI/CD — backed by 1,520 automated tests.
ATM Log Aggregation, Anomaly Detection & Diagnostics Platform
Started as a university team project, rebuilt and extended solo over the summer. Kafka ingestion through 3-layer ML/statistical/heuristic detection, a LangGraph agentic RAG assistant with a System One (TypeSafe Jev) typed-decision layer, full AWS/Terraform deployment, OpenTelemetry/Jaeger distributed tracing across services, and 1,974 automated tests.
SWE-Qwen
LLMOps platform turning 20,477 SWE-bench issues into a 17,456-example training corpus, 3 QLoRA variants of Qwen3-14B fine-tuned on Modal A100s, execution-based evaluation (17.20% fail-to-pass vs 2.46% base, 7.0×) with statistical champion/challenger gating, served via an OpenAI-compatible inference API — plus a CLI model registry that onboards any open-weight Hugging Face model with per-model quantization, context, and GPU config, gated by 1,541 automated tests.
WikiStream
Real-time streaming analytics platform ingesting every public Wikipedia edit via SSE into self-hosted ClickHouse, live dashboards, hourly warehouse exports, 58.9M+ events with zero drops in a 10× synthetic burst (5,655 events/sec), verified by 176 automated tests.
Coursework
Haggis Predictive Modeling
End-to-end ML pipeline: EDA, feature engineering, XGBoost and Random Forest modelling. Achieved ~90% classification accuracy, validated with F1-scores and cross-validation.
Unix Version Control System
Git-like VCS in pure Bash - check-in/out with file locking, timestamped backups, automatic diffs and filterable audit log. Zero deps beyond Unix utils.
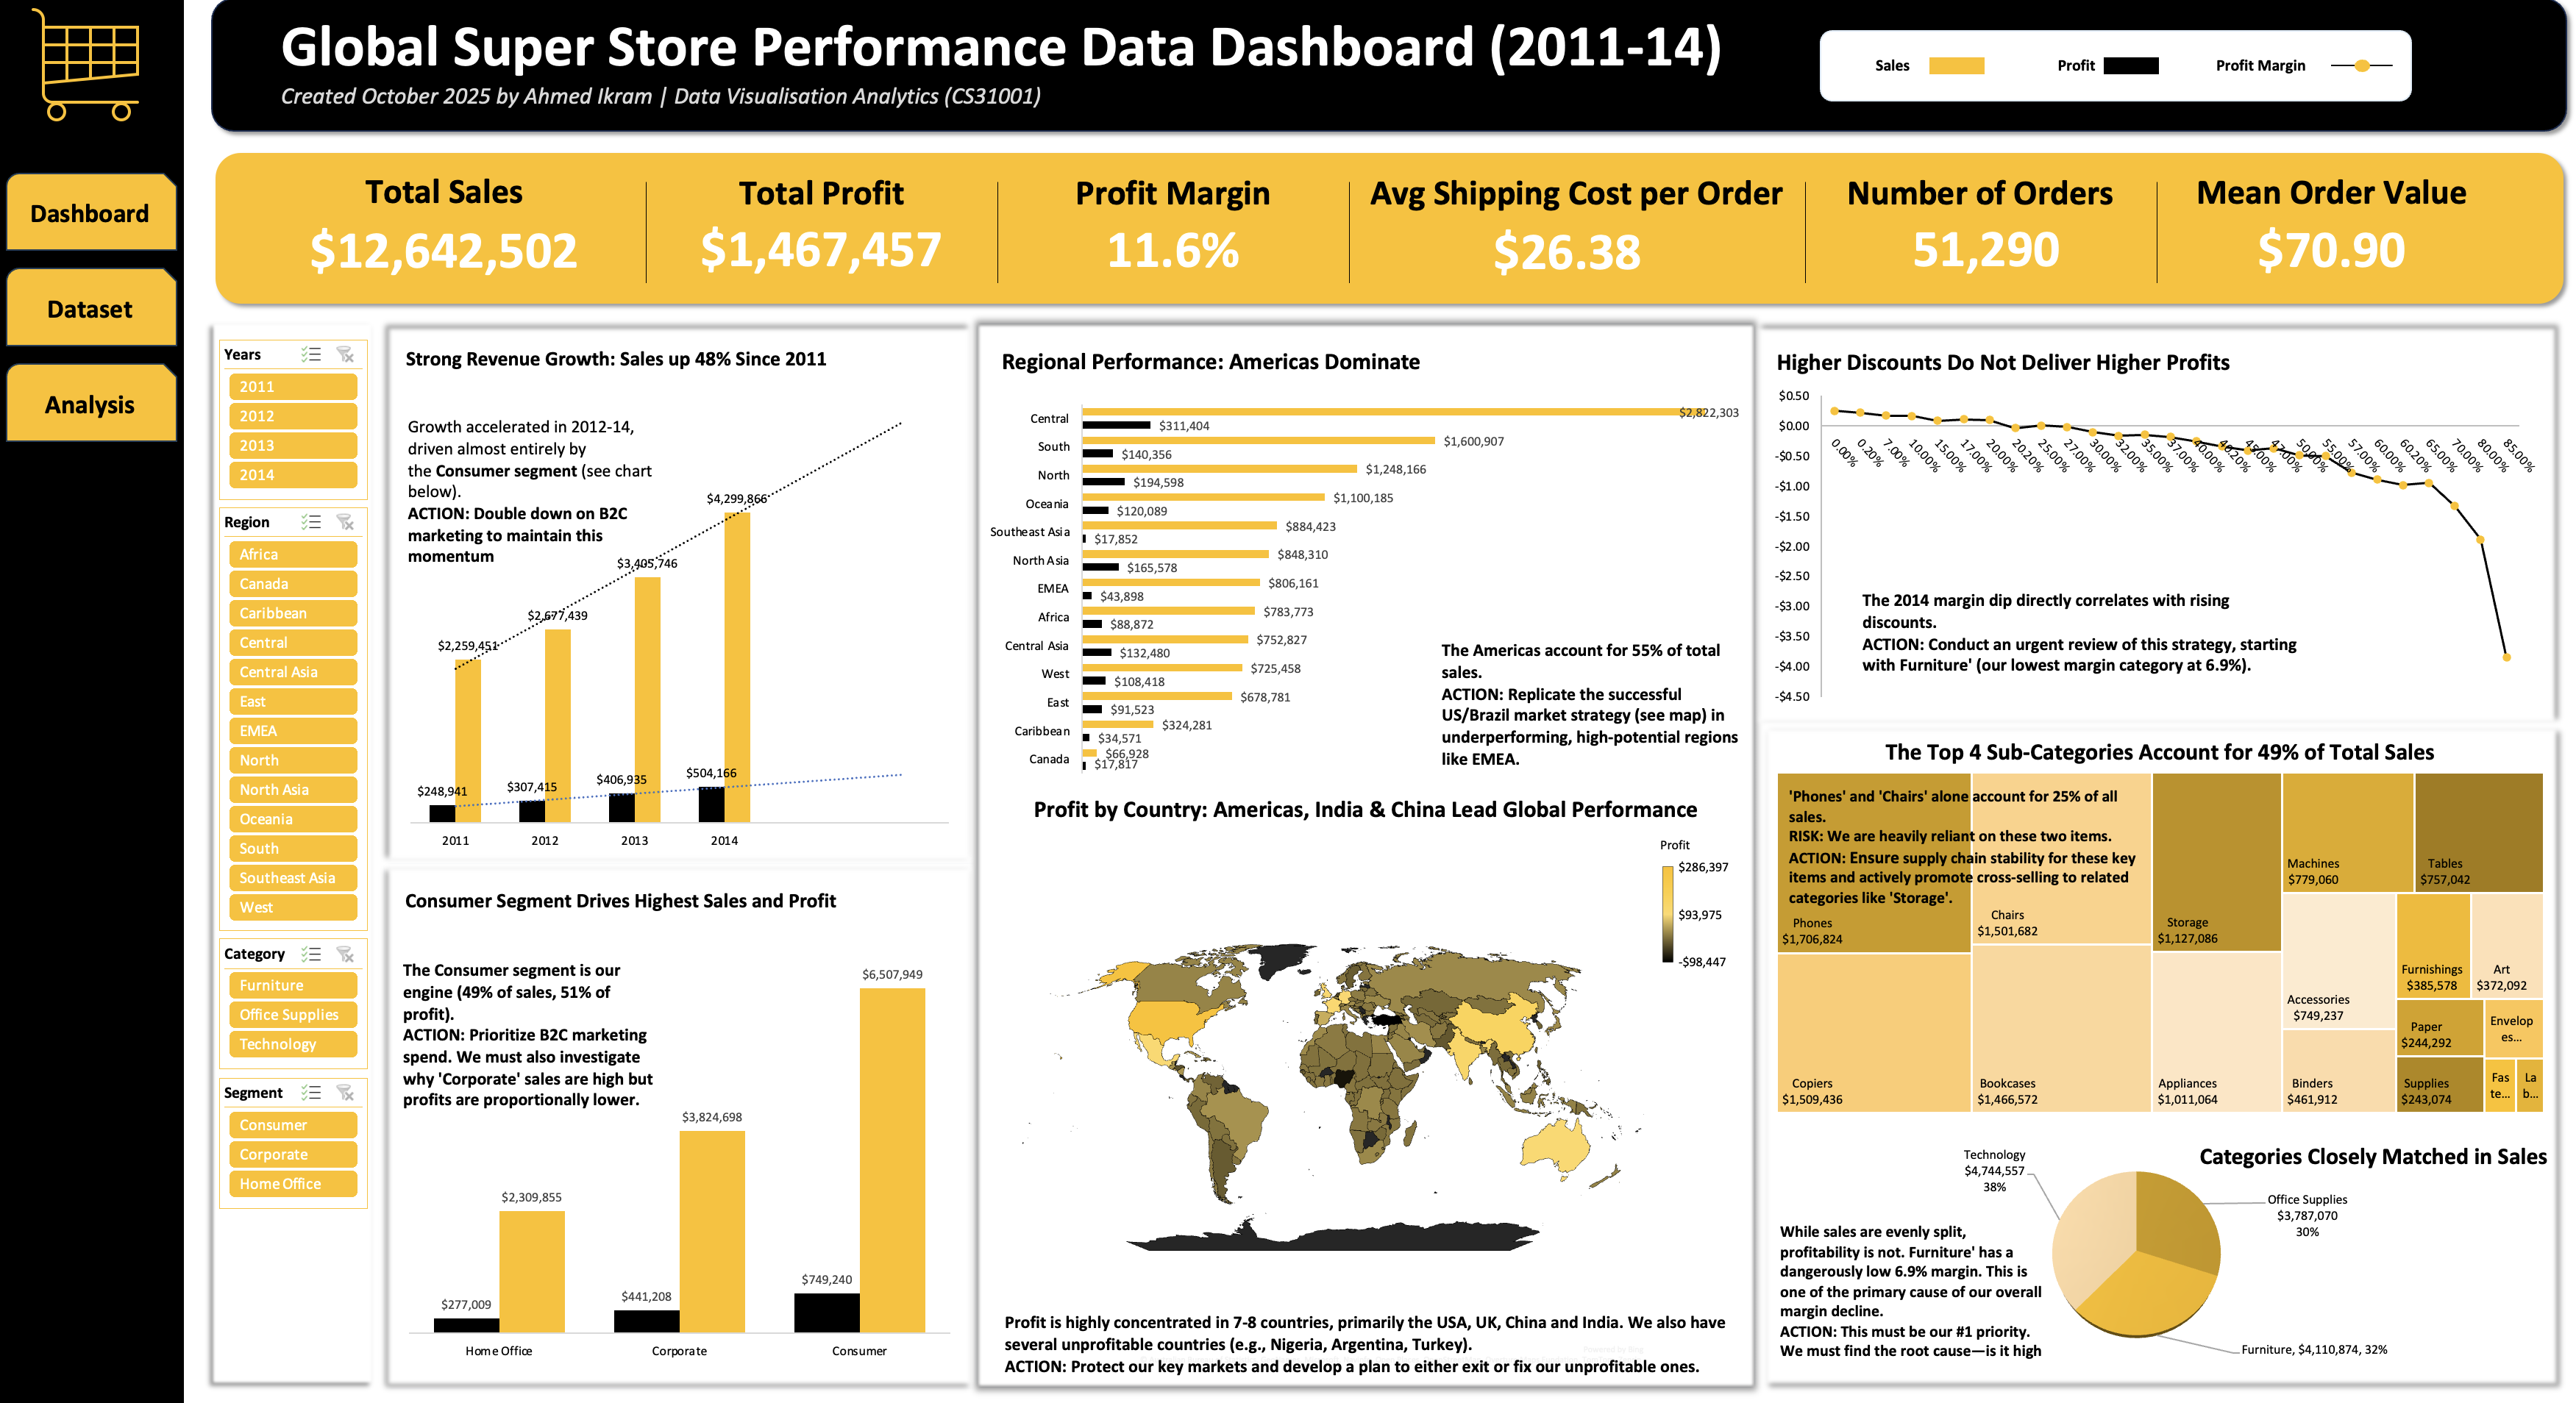
Business Performance Case Study Dashboard
Interactive performance analytics dashboard with data visualisations, trends, insights and KPIs
Case Study: LAAD
An ATM log aggregation, anomaly detection and diagnostics platform built for NCR Atleos.
The Problem
NCR Atleos ATMs generate MBs of log data each day across several sources, application logs, hardware sensor metrics, terminal handler logs, Kafka, Prometheus, Windows OS and GCP cloud metrics. Field engineers are flying blind: faults surface only after customers report them, and root-causing a single ATM meant grepping millions of unstructured lines by hand.
My Role, Solo Builder
LAAD began as part of a 7-person university team project. After the module ended, I continued developing it independently throughout the summer and substantially rebuilt the system. The original submission had basic rule-based detection and a simple database-writing generator, the majority of the current architecture was designed, implemented and deployed by me alone.
- 2.5M events every 24 hours at ~100 messages/second with zero loss
- 0.92 held-out macro-F1 on the XGBoost detection ensemble — 0.94 on a temporal holdout, 0.93 on a held-out second generator configuration
- 0.708 context recall from the agentic RAG assistant, 2× the deterministic baseline
- Typed decisions at ~$16 per 1M via a System One layer (TypeSafe Jev) — judgments 18× cheaper, 83% agreement with human verdicts
0.92
XGBoost held-out macro-F1 across 8 anomaly classes — 0.94 on a temporal holdout, 0.93 on a second generator configuration
2×
RAG context recall vs the deterministic baseline, 0.708 vs 0.350 on a 50-query golden set
1,974
Automated tests: 1,439 pytest, 495 vitest, 10 Playwright E2E, 30 Terraform assertions
2.5M
Events processed at ~100 msg/sec with zero loss, gzip-compressed ~65% on the wire
30
REST API endpoints behind JWT auth, role-aware access and Redis rate limiting
94%
Isolation Forest precision on live Kafka traffic, F1 0.61, AUC-ROC 0.78
Pipeline & Architecture
Seven heterogeneous sources stream into a continuous Kafka producer (gzip, acks=all, retries 5), land on two KRaft topics with 7-day retention, and are consumed by a pipeline that deduplicates, parses, dual-writes to PostgreSQL and a ChromaDB vector store, and feeds a detection engine every 30 seconds, surfaced through a FastAPI backend and a React dashboard.
- Ingestion, Kafka KRaft, 2 topics × 3 partitions, ~65% gzip compression (250KB/s → 85KB/s on the wire), 3.5GB/day → 1.2GB/day on disk
- Reliability, dedup via Redis SET + 10K in-memory LRU, manual offset commits, failed messages land on a Redis Stream DLQ with exponential backoff (5s → 10s → 20s)
- Schema-on-read storage, PostgreSQL 16 with JSONB payloads: adding a new source means adding a parser, never a migration. 10 tables, 3 views, 15 indexes, hourly retention cleanup
- Vector store, ChromaDB with semantic chunking and local 768-dim embeddings for the RAG assistant
- API, FastAPI, 30 endpoints across 6 routers, JWT auth and 8 Redis patterns (rate limiting, caching, locks, Pub/Sub, DLQ) with graceful degradation
End-to-end flow: 7 log sources → Kafka → 3-layer detection → API → React dashboard
The 3-Layer Detection Engine
Layer 1, ML Ensemble
- XGBoost: 48 engineered features in 7 groups, 8 anomaly classes, 99.0% cross-validated accuracy, 0.92 held-out macro-F1
- Isolation Forest on the 46 highest-importance features: AUC-ROC 0.78, 94% precision, F1-maximising threshold from a 200-point sweep
- Known faults at confidence ≥ 0.70; novel patterns flagged as UNKNOWN
Layer 2, Statistical Drift
- Rolling 20-window median/std baseline; alert on |z| > 3.0
- Catches concept drift and unseen behaviours with zero model dependency
- Confidence from the z-score magnitude, no training data required
Layer 3, Heuristic Rules
- 7 deterministic detectors (A1–A7): network timeouts, cash cassette faults, JVM memory leaks, container restarts, response spikes, OS memory pressure, out-of-order Kafka
- 10-minute dedup window per (anomaly type, ATM)
- A live SageMaker champion endpoint cross-checks predictions without overriding them
All 3 layers in action: ML ensemble, z-score drift and heuristic alerts surfacing in the anomaly list
Agentic Hybrid RAG
A LangGraph agent with 12 MCP tools answers operator questions over the anomaly corpus: ChromaDB retrieval with metadata filters and temporal decay, cross-encoder reranking, then a 4-stage reasoning loop, self-consistency sampling, verbalised confidence, reflexion and citation grounding, fused into a single score (0.30 retrieval + 0.25 self-consistency + 0.25 verbalised + 0.20 grounding) via uncertainty-weighted averaging with static calibrated weights.
| RAGAS Metric | Fixed Retrieval | Hybrid Agent | Agentic Agent |
|---|---|---|---|
| Context Recall | 0.533 | 0.350 | 0.708 |
| Context Precision | 0.711 | 0.645 | 0.874 |
| Faithfulness | 0.982 | 0.908 | 0.940 |
| Answer Relevancy | 0.650 | 0.602 | 0.801 |
Evaluated on a 50-query golden set (82% human-reviewed) with a committed baseline and a CI gate that fails any PR with faithfulness < 0.9, context recall < 0.3, or a drop > 0.05 vs baseline.
Diagnostic conversation: confidence breakdown and grounded citations on live anomaly data
Delivery & Observability
- 1,974 automated tests, 1,439 pytest (10 tiers), 495 vitest (41 suites), 10 Playwright E2E, 30 Terraform assertions, with Codecov and a checkov-hardened IaC pipeline
- Zero-trust deployment, 6 least-privilege IAM roles (OIDC-based CI/CD, ECS, SageMaker, CloudWatch, MLflow), 8 secrets injected from Secrets Manager, no long-lived credentials
- MLOps, MLflow on RDS with S3 artifact storage, champion alias promotion, auto-retrain on corruption, every run tagged with its git SHA
- Observability, vendor-neutral OpenTelemetry tracing across 4 services via OTel Collector → Jaeger (dev) on 2 golden paths with W3C context through Kafka headers; AgentTrace table, Redis Pub/Sub alerts, CloudWatch + Grafana dashboards
My Experience
A comprehensive overview of my professional journey, academic achievements, certifications, and technical skills that shape my expertise in software development.
Work Experience
Beauly Mini Market
Retail Assistant • September 2023 - Present
Zulus Peri Peri Grill Dundee
Front of House • June 2021 - September 2023
Education
University of Dundee
BSc (Hons) Computer Science (Data Science and AI) • September 2023 - June 2027 (Expected)
High School of Dundee
Secondary Education • August 2018 - June 2023
Certifications
AWS Academy Graduate - Cloud Foundations
2024
- Hands-on experience with AWS services: EC2, S3, RDS, IAM, Elastic Beanstalk
- Deployed and managed scalable cloud infrastructure with auto-scaling and load balancing
- Gained knowledge in cloud security, cost optimization, and best practices
AWS Academy Graduate - Machine Learning
2025
- Learned machine learning fundamentals using AWS AI/ML tools (Amazon SageMaker)
- Hands-on experience with data preprocessing, model training, and evaluation
- Applied ML models to real-world scenarios in a cloud environment
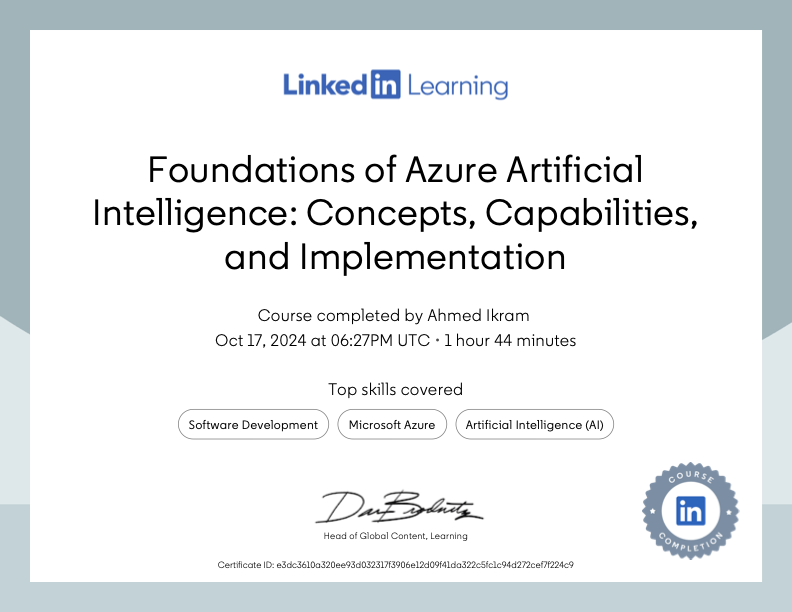
Foundations of Azure Artificial Intelligence
2024
- Explored Azure AI services: Computer Vision, NLP, and Cognitive Services
- Implemented AI models in cloud-based applications
- Understood AI ethics and responsible deployment
Core Skills
AI Engineering
Data Engineering
Software Engineering
Technical Skills
Programming Languages
Web & Mobile Development
Backend Frameworks & APIs
Databases & Storage
Data Science & ML
AI & LLM Engineering
Data Engineering
Cloud & DevOps
Testing & Tools
Security & Code Quality
My CVs
I have three role-specific CVs depending on the type of role you may be hiring for. Preview the versions below.
Get In Touch
I'd love to hear from you! Whether you have a project in mind, want to collaborate, or just want to say hello, feel free to reach out through any of the channels below.